
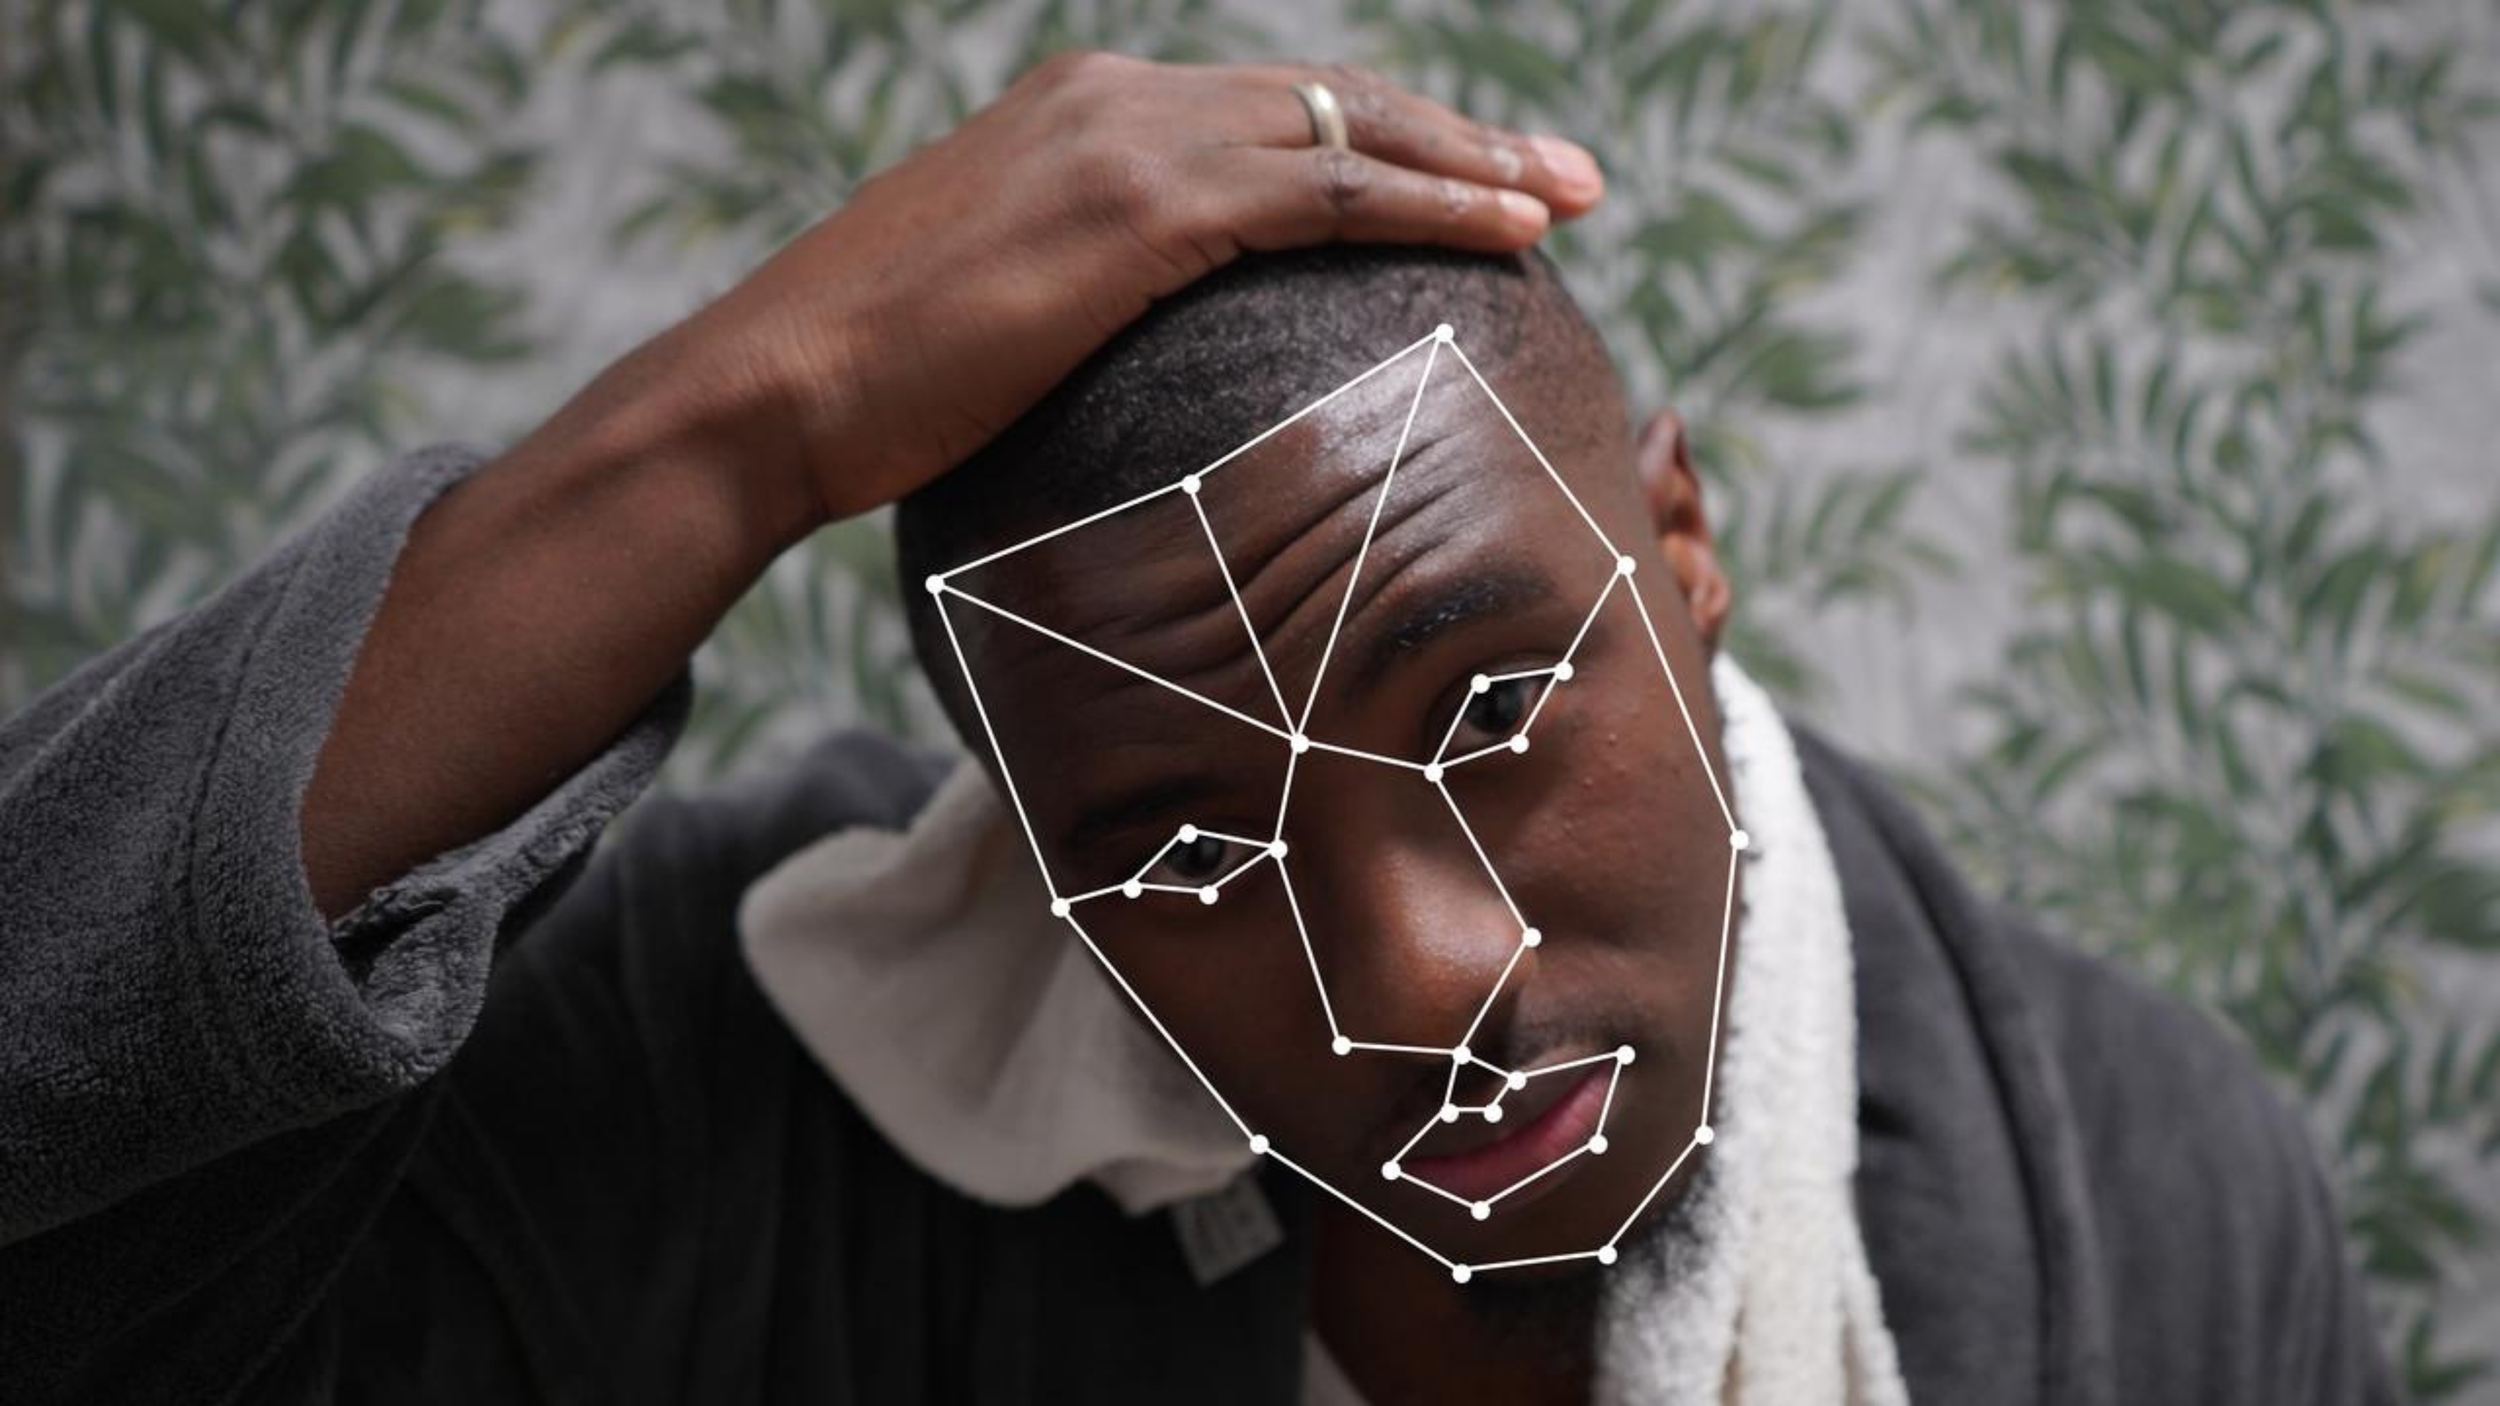
Comuzi / https://betterimagesofai.org / © BBC / https://creativecommons.org/licenses/by/4.0/
A note from nfpPublic Minority Ethnic Lead Leiyuan Tian:
“Over the summer, I worked on redeveloping our annual research with minoritised ethnic communities in the UK. As part of this process, I spoke to many charities about their current work and future plans to deepen their engagement with underserved audiences. In these conversations, one question came up repeatedly: how to encourage people from minoritised ethnic backgrounds to take part in research? Some charities I spoke to felt that it was a matter of reach: low participation meant that their organisations simply weren't doing enough to gain visibility within these communities. While this might be true in some cases, today’s guest blog from Mark Wong shows there can be more to it.
Mark’s blog highlights that hesitancy to share ethnicity data, or to take part in research at all, often comes from lived experience of personal data misuse. Adversely racialised people have seen institutions collect and use their data in ways that worked against their interests, and that historical as well as ongoing experience has resulted in a lasting distrust. Consequently, if we want to encourage research participation, we need to start by understanding this wider context and building it into how we design our research.
For charities looking to understand underserved audiences, this blog offers practical recommendations and a guiding principle to reflect on: we should do research with people, not on people. At nfpResearch, these are the things that have shaped our thinking around how we can improve our own research, and we hope this blog will open up a wider conversation about empowering minoritised ethnic communities through inclusive, cooperative research.”
By Prof. Mark Wong, Professor of Social and Digital Policy, University of Glasgow
The global fight against systemic racism and racial injustice is more urgent than ever. Growing racial inequalities are found in many domains such as health, while political tensions around the far-right are manifesting through violence and racist riots, including recently in the UK.
This has led to growing efforts of public and third sector organisations to use and collect ethnicity data to inform their work and raise awareness of racial justice issues.
However, ethnicity data is not only sensitive personal information but also uniquely intertwined with a troubled, but under-discussed, history of “race” science, which requires deeper understanding before use to prevent inadvertently reinforcing racism.
If not careful, ethnicity data collection and use can cause harms by perpetuating racial hierarchies and ideologies of “race” as a biological fact instead of a social construct.
History of “Race” and Data
A new documentary, “Ghost in the Machine”, highlights how AI systems and data practices can embed racial logics. This is echoed in Prof. Ruha Benjamin’s book, which warns statistics, measurements, and data systems have long been a tool for control and a mechanism to reinforce colonialism and racism. Data is and has always been deeply political.
This is important because the design of data systems has been instrumental to embed the ideologies of “race”, including how “race” and ethnicity are recorded, collected, and analysed. So if actions are not taken to safeguard ethnicity data collection and analysis, these practices will cause further harm by dehumanising, other-ing, and reinforcing the concept of “race” and racial hierarchies.
“If actions are not taken to safeguard ethnicity data collection and analysis, these practices will cause further harm by dehumanising, other-ing, and reinforcing the concept of “race” and racial hierarchies.”
To address this, organisations need to start by reflecting on the complexities that come with the collection and analysis of ethnicity data before using it.
Ethnicity data should be handled with care and safeguards developed from an anti-racism approach. This helps to address the risks of perpetuating racism in how ethnicity data is used, including in AI systems, which I have written about recently in a blogpost.
Centering Lived Experience Expertise and Co-design
An anti-racism approach necessitates the sharing of power with people and communities who are harmed and most negatively affected. As championed by leading scholars such as Patricia Hill Collins, affected communities must be regarded as knowledge co-creators as opposed to ‘subject’ of study.
We should start by valuing expertise by lived experience in our data practice. Experts by lived experience should be at the heart of designing and making decisions about how data is used and collected in our organisations, and not only by technical experts.
This is where a co-design approach with adversely racialised communities can be ‘game-changing’ to counter the power imbalance typically found in digital and AI transformation. This community-led approach is highlighted in a recent NHS Race and Health Observatory’s briefing paper, which provides recommendations on designing trustworthy, equitable AI and data systems with experts by lived experience.
So, when reflecting on how ethnicity data is used in our organisation, we need to ask: who is in control? Whose views and concerns are listened to? And whose expertise are valued in decision-making about how, why, and when ethnicity data should be used or not?
“Experts by lived experience should be at the heart of designing and making decisions about how data is used and collected in our organisations”
‘Dilemma’ of Ethnicity Data Collection
Another key consideration of ethical use of ethnicity data is understanding barriers and gaps in ethnicity data collection and how they are intertwined with experiences of racism.
In recent research I led at the University of Glasgow, our work in Scotland and England revealed new understandings about adversely racialised people’s concerns and experiences when ethnicity data is collected.
Firstly, being asked about ethnicity can be a particularly high-stake dilemma for adversely racialised individuals. Many individuals had a strong understanding of the benefits of giving their data for equality monitoring and service improvement. However, many felt conflicted about when to disclose their ethnicity, as disclosing ethnicity can increase risks of being discriminated by the organisations or individuals collecting the data. Many people, therefore, choose broadest categories or ‘prefer not to say’ as a self-protection mechanism from racism and harm.
Secondly, many participants were concerned about data theft and misuse, while question unclear purpose of ethnicity data collection. They were concerned about doing the ‘wrong thing’, which could have disproportionately negative consequences on adversely racialised individuals who are often over-penalised in many settings. As a response, people give inconsistent reply to ethnicity questions, selectively sharing and modifying ethnicity information, or refuse information and services altogether even in times of need.
Thirdly, poor prior experiences of racism and low institutional trust can lead to fear of repercussion. Many individuals we interviewed were burdened by risks of stereotyping, discrimination, and ‘everyday racism’ as part of their lived realties of being racialised. So individuals are worried about being disadvantaged or discriminated every time ethnicity data has potentials to be misused.
Good Practice of Ethnicity Data Collection
Our research recommends that understanding and valuing expertise by lived experience in designs of ethnicity data collection is crucial:
Allow selective, inconsistent, and optional disclosure of ethnicity within and across different data sources, so people’s self-protection mechanism from racism and harms is preserved.
Ethnicity data should not be treated as a fixed, static biological category but a contextually-dependent information that can change over time. Self-reporting should be prioritised and editing (and removal) of ethnicity data by users need to be built in early.
The ethnicity information specified should not be aggregated into higher-level categories without individual consent. This practice, despite being commonly used in statistics, risks reinforcing racial ideologies and racism.
These recommendations have since been successfully adopted and informed the code of practice of public health authorities and government analysis using ethnicity data in Scotland. It is crucial that more organisations working with ethnicity data improve awareness and take into account its underlying social-cultural contexts, so racism and racialisation are not perpetuated.
We have to get this right, and empower the people who are most affected, so that people’s rights to exercise agency and choice are respected and the future of data and AI equitable and trustworthy for all.